FROM THE NOTEBOOK
MCP 协议简介
概述#
MCP(Model Context Protocol) 是 Anthropic 在 2024 年 11 月推出的开源协议,用于将 AI 连接到外部的应用程序上,本质上是一个标准,规定了应用程序应该如何向 LLM 提供上下文。
出现 MCP 的一大重要原因可能是提示词工程(Prompt Engineer)被认为非常重要(这甚至出了一门 课程),调教好的提示词,更完善且结构化的上下文信息,能够显著提升 LLM 的输出/行为。
协议架构#
MCP 的架构为传统的 B-S 架构,主要包含三个部分:
- Host:带有 AI 功能的 IDE/编辑器
- Server:提供具体工具/数据访问功能的组件
- Client:被内置在 Host 中,用于与恰当的 Server 建立连接
我们用下图来表示其工作流程:
mermaid 视图暂不支持。
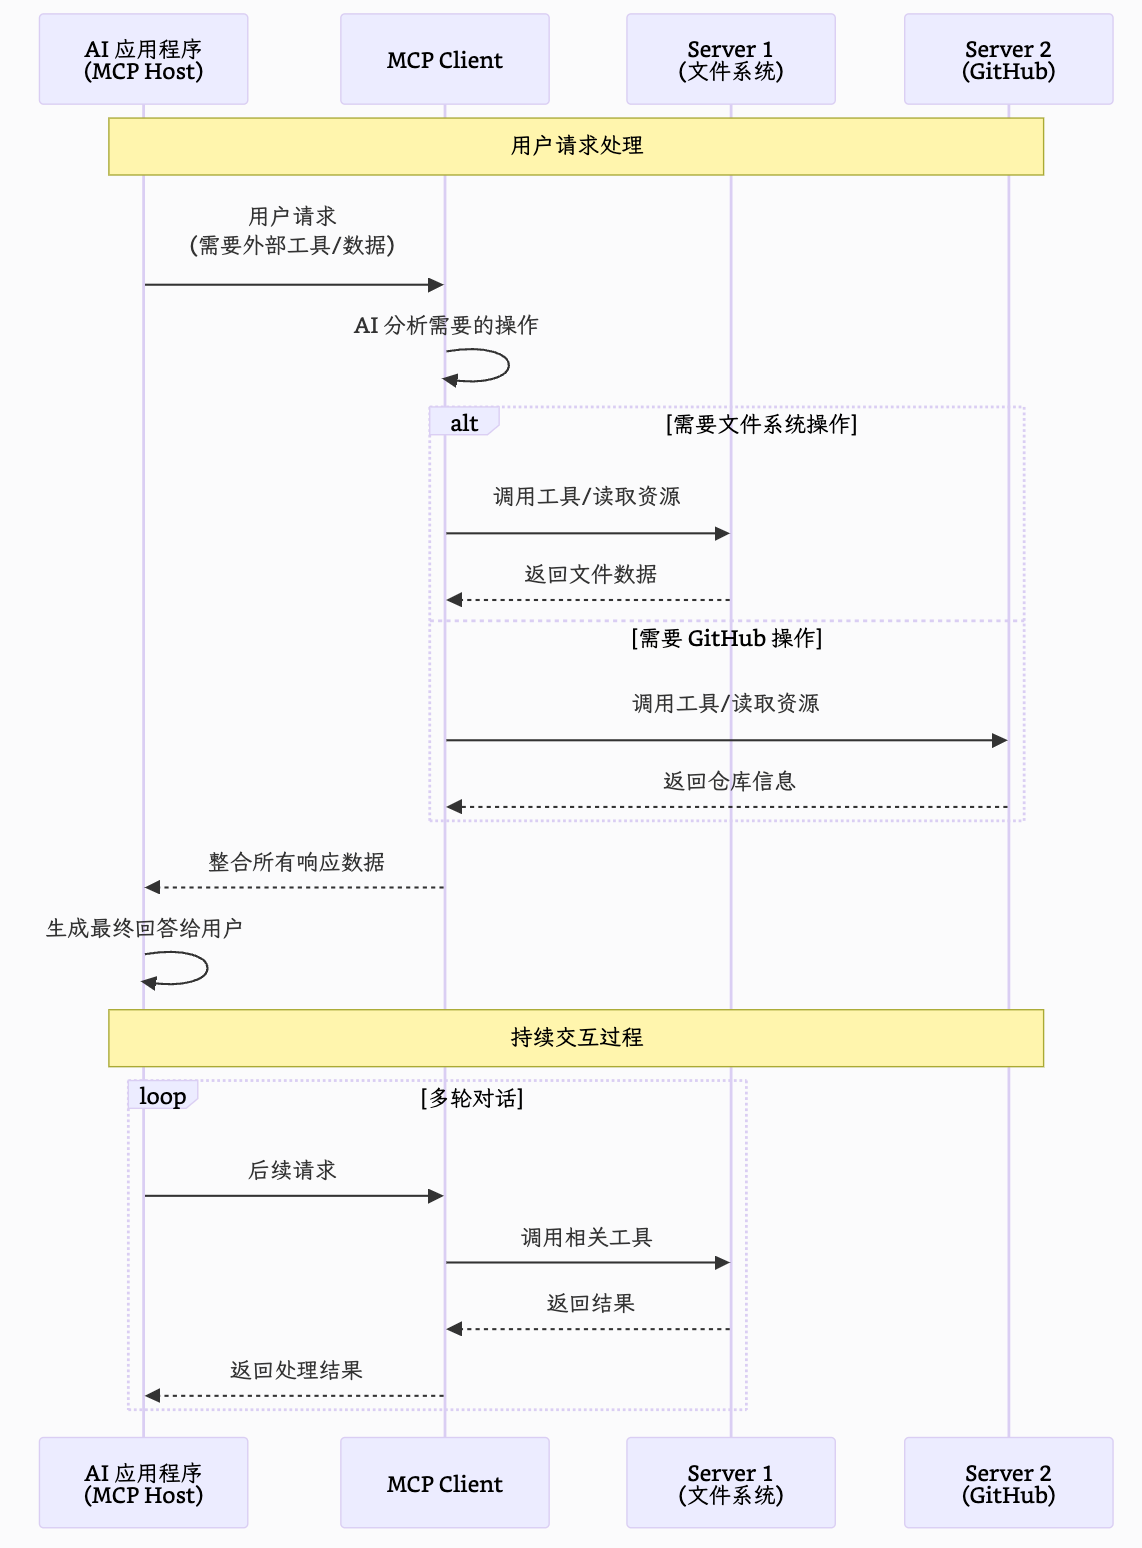
在这种架构下,开发者只需要专注开发 Server 即可,不需要关心 Host 和 Client 是如何实现的
那么就会引出一个很重要的问题:AI 如何确定自己选择对了 MCP 服务?
我们可以根据 代码 来解释:
class ChatSession:
    """Orchestrates the interaction between user, LLM, and tools."""
    async def start(self) -> None:
        """Main chat session handler."""
        try:
            for server in self.servers:
                try:
                    await server.initialize()
                except Exception as e:
                    logging.error(f"Failed to initialize server: {e}")
                    await self.cleanup_servers()
                    return

            all_tools = []
            for server in self.servers:
                tools = await server.list_tools()
                all_tools.extend(tools)

            tools_description = "\n".join([tool.format_for_llm() for tool in all_tools])

            system_message = (
                "You are a helpful assistant with access to these tools:\n\n"
                f"{tools_description}\n"
                "Choose the appropriate tool based on the user's question. "
                "If no tool is needed, reply directly.\n\n"
                "IMPORTANT: When you need to use a tool, you must ONLY respond with "
                "the exact JSON object format below, nothing else:\n"
                "{\n"
                '    "tool": "tool-name",\n'
                '    "arguments": {\n'
                '        "argument-name": "value"\n'
                "    }\n"
                "}\n\n"
                "After receiving a tool's response:\n"
                "1. Transform the raw data into a natural, conversational response\n"
                "2. Keep responses concise but informative\n"
                "3. Focus on the most relevant information\n"
                "4. Use appropriate context from the user's question\n"
                "5. Avoid simply repeating the raw data\n\n"
                "Please use only the tools that are explicitly defined above."
            )

            messages = [{"role": "system", "content": system_message}]

            while True:
                try:
                    user_input = input("You: ").strip().lower()
                    if user_input in ["quit", "exit"]:
                        logging.info("\nExiting...")
                        break

                    messages.append({"role": "user", "content": user_input})

                    llm_response = self.llm_client.get_response(messages)
                    logging.info("\nAssistant: %s", llm_response)

                    result = await self.process_llm_response(llm_response)

                    if result != llm_response:
                        messages.append({"role": "assistant", "content": llm_response})
                        messages.append({"role": "system", "content": result})

                        final_response = self.llm_client.get_response(messages)
                        logging.info("\nFinal response: %s", final_response)
                        messages.append({"role": "assistant", "content": final_response})
                    else:
                        messages.append({"role": "assistant", "content": llm_response})

                except KeyboardInterrupt:
                    logging.info("\nExiting...")
                    break

        finally:
            await self.cleanup_servers()
可以发现我们是通过 prompt 确定了当前有哪些工具,然后将工具的名字,描述(用途)和参数输出为一个 json-rpc 2.0 的形式,统一传入到 system_message 中,这样我们的 LLM 就能够识别有哪些工具,并自主选择合适的工具来完成用户的请求。
讨论
想法、补充,或只是打个招呼。